The Runtime Authority Problem: From Granted Permissions to Enforced Execution Boundaries
Why Enterprise AI Agents Require Runtime Authorization, Execution-Level Enforcement, and Verifiable Control
The "runtime authority problem" in enterprise AI agents addresses the critical gap between system access and ensuring authorized actions at the point of execution.
Opinion · AI-assisted, human edited
Executive Summary
AI agents are evolving beyond simple question-answering capabilities. Equipped with various tools and permissions, they can now retrieve information, update records, call APIs, create documents, and initiate business processes. This expansion of capabilities raises a critical question for every enterprise: How can an organization ensure an AI agent performs only authorized actions at the moment those actions are executed?
Granting an AI agent access to a system does not imply that every action it requests should be permitted. For instance, an agent might have permission to read customer records, but this does not automatically authorize it to modify customer details, approve payments, or delete records. This principle remains valid when an agent utilizes multiple tools, operates across several business systems, or continues a task after its permissions have changed.
This challenge is known as the "runtime authority problem." It represents the gap between providing an agent system access and guaranteeing that each action it performs remains within its authorized limits. While established security approaches, such as the National Institute of Standards and Technology's (NIST) Zero Trust Architecture, offer foundational solutions by evaluating access to resources rather than trusting users or systems implicitly [1], enterprise AI introduces new complexities.
New questions arise: What if an agent selects an unexpected tool? What if a permission is revoked mid-task? Can an organization halt an action that has already commenced? And how can an organization verify what actually transpired? These inquiries demand more than just access management.
This article explores the runtime authority problem and proposes an architectural solution based on five core principles: - Define authority clearly. - Check permissions at the point of execution. - Enforce limits independently of the AI agent. - Control behavior when permissions change. - Maintain verifiable evidence of decisions, execution, and outcomes.
The objective is not to eliminate AI autonomy but to ensure it operates within well-defined, enforceable, and reviewable boundaries.
From Access Permission to Execution Authority
Traditional access management addresses a fundamental question: Who or what is authorized to access a specific resource? For example, a system might allow an employee to view financial records or an application to retrieve customer data.
AI agents introduce a more granular question: Which specific actions may this agent perform, under what conditions, and with what limitations? While related, these questions are distinct.
Consider an AI agent integrated with an enterprise accounting system. The organization might permit the agent to: - Read invoices. - Compare purchase orders. - Identify missing information. - Prepare reconciliation reports. - Recommend corrections.
However, the organization might explicitly prohibit the agent from: - Approving its own recommendations. - Changing supplier bank details without additional verification. - Releasing payments without required approval. - Overriding financial controls. - Expanding its own permissions.
Even if an agent has technical access to the accounting system, that access should not automatically translate into unlimited business authority. This distinction is particularly crucial when an agent can leverage multiple tools or when an action impacts other systems. An agent might be allowed to read a record in one application but not modify the same record in another. It might be permitted to prepare a payment request but not to authorize the payment itself. A secure design must explicitly represent these differences.
Three critical questions must remain distinct: | Question | What it means | | :------- | :------------ | | **Capability** | What can the agent technically do? | | **Authority** | What is the agent allowed to do? | | **Execution** | What action did the system actually perform? |
These three questions are not interchangeable. Technical capability does not equate to permission, and permission does not serve as proof of execution. This principle forms a central foundation for governing AI agents within enterprise environments.
The Permission–Execution Gap
The permission–execution gap arises when the system granting permission cannot enforce those intended limits at the actual point of action.
Imagine an enterprise granting an agent access to a customer management system, allowing it to read records and update specific fields. The agent's access token remains valid for a period. During this time, the organization's policy changes, revoking the agent's permission to update customer information.
Despite the policy change, several questions persist: - Has this policy change propagated to all relevant systems? - Will the next request from the agent be denied? - Could another tool still accept the old permission? - Could a previously approved operation continue running? - Will the system log the change and its impact?
The answers depend entirely on the system's design and implementation. A policy change, by itself, does not guarantee that every downstream system has ceased accepting previously authorized operations. NIST's Zero Trust Architecture offers a valuable framework by separating policy decisions from enforcement and emphasizing controlled access to individual resources [1].
The architectural lesson is straightforward: a permission must be linked to an enforcement mechanism capable of rejecting actions that fall outside the current policy. Without this connection, a policy might exist on paper while actual execution remains inadequately controlled.
Why AI Agents Make This Harder
An AI agent's operation often involves several components: - An AI model selects a tool. - An agent framework prepares a request. - A gateway or application sends the request. - An identity system provides credentials. - A target application processes the request. - Another system may trigger a follow-up action.
Each component has a distinct role. While the model may decide its intended action, the model's decision alone should not dictate whether the organization permits that action. That determination rests with the applicable authorization and enforcement controls.
What Runtime Authority Means
Runtime authority is the permission to perform a specific action under the conditions that are current at the moment the action is attempted. The term "runtime" is crucial because permissions and operating conditions can change dynamically while a system is active.
A robust authorization decision should consider more than just the agent's identity. Depending on the risk level, it may also need to account for: - The specific action requested. - The resource being affected. - The data involved. - The business purpose. - The agent's assigned role. - The applicable policy. - The current approval status. - The potential impact. - The state of the task. - Whether the action can be reversed.
For example, an agent might be allowed to prepare a purchase order but not submit it until an authorized person approves it. The same agent might be permitted to automatically submit a low-risk internal request, provided it remains within an approved limit. This is not a contradiction; it reflects a distinction between different levels of authority.
A Practical Authority Model
An enterprise can define four broad decision levels for AI agents: | Level | Meaning | | :---- | :------ | | **Recommend** | The agent may suggest an action. | | **Decide** | The agent may select an action within defined limits. | | **Execute** | The agent may carry out an authorized action. | | **Hold or escalate** | The system must pause or request human intervention. |
These levels should be assigned based on business risk, policy, and organizational responsibility, not solely on the perceived capability of the AI model. A highly capable model may still lack the authority to approve a transaction. Similarly, an agent with permission to execute a task should not automatically gain permission to alter the rules governing that task. While an agent's capabilities may expand, its authority must always remain explicitly defined.
Why Authorization Must Be Enforced Outside the Agent
While an AI agent can be instructed to follow a policy, such instructions alone should not be considered the ultimate security boundary. An agent might misinterpret a request, receive misleading information, select an incorrect tool, or generate an action inconsistent with the organization's intent. Therefore, critical restrictions must be enforced by systems that control access to relevant resources and actions.
NIST's Zero Trust model supports this general design principle through its use of policy decision and enforcement components [1]. For an enterprise AI architecture, this implies a separation of responsibilities.
The Model Proposes; The Control Layer Authorizes
A controlled execution flow could appear as follows: User request → AI agent → Proposed action → Authorization check → Enforcement point → Target system → Execution record
The exact components will vary by implementation. The crucial requirement is that the action must pass through an enforcement mechanism before it reaches the protected operation. For high-impact actions, the authorization check might need to verify that a required human approval has been recorded. For a prohibited action, the enforcement mechanism should reject the request. For an action exceeding the agent's limits, the system should hold or escalate the request. In uncertain situations, the system should not assume permission exists simply because the agent can formulate the request.
Why This Separation Matters
If the agent can freely choose its tools and directly control their permissions, the organization may struggle to enforce independent limits. A more robust design separates: - The AI's ability to propose an action. - The policy's authority to approve or reject it. - The enforcement mechanism's ability to allow or block it. - The evidence system's ability to record what occurred.
These functions may be implemented by different components or combined in a carefully designed system, but their distinct responsibilities should always be clear.
Revocation Does Not Automatically Stop Every Action
Revocation, the withdrawal of a permission, credential, token, or authorization grant, is an important security control. However, revocation and execution control are not identical.
This distinction is evident in OAuth 2.0 Token Revocation (IETF RFC 7009), which specifies how clients can request an authorization server to revoke access or refresh tokens. It also clarifies that the effect of revocation depends on implementation details, including how access tokens are validated. Some systems may experience a delay before all relevant components acknowledge a token's revocation [2].
This has significant implications for AI agents. Revoking a credential does not, by itself, guarantee that every action already in progress has halted.
Consider a business process with multiple stages: - An agent receives permission to update a record. - The agent submits a request. - The target system accepts the request. - The target system begins processing it. - The organization withdraws the agent's permission.
The operation might still be running or may have already completed. The outcome depends on the operation's current stage and how relevant systems handle revocation. Stopping new requests differs from halting work already accepted by a target system. Stopping a running operation differs from reversing an action that has already modified business data. A mature architecture must differentiate these cases.
Four Areas to Consider
| Area | Key question | | :--- | :----------- | | **Credentials** | Can the agent continue using its existing access token? | | **Execution** | Can a new request be blocked, and can running work be stopped? | | **Business effects** | Has the action already changed a record or triggered another process? | | **Evidence** | Can the organization establish what happened before and after revocation? |
These areas are interconnected but require different controls. For example, a system might successfully invalidate a token while being unable to reverse a payment that has already been processed. Similarly, a cancellation request might stop a queued job but fail to stop an operation that the target system has already completed. Therefore, the organization should define the expected behavior for each stage of execution.
The Containment Problem
Containment refers to limiting the impact of an unwanted or unauthorized action. In an AI-enabled enterprise, containment should not solely rely on the agent recognizing a mistake. It must also depend on external controls surrounding the agent.
Possible controls include: - Restricting the tools an agent can call. - Limiting the records it can access. - Blocking prohibited operations. - Requiring approval for high-impact actions. - Limiting the number or value of transactions. - Separating preparation from approval. - Halting further execution upon detecting a policy violation. - Monitoring actions across interconnected systems.
These controls should be chosen based on the associated risk and the systems involved. For instance, an agent that drafts internal reports may require fewer restrictions than one that can alter financial records. The principle is not that every action needs human approval, but that the level of control must correspond to the potential consequences.
Why the Target System Matters
Suppose an agent sends an instruction to an external business system. The agent's own interface might indicate that it has canceled the task. However, the external system may have already accepted the instruction. The agent's self-report is insufficient to confirm that the external action has stopped. The organization requires evidence from the component responsible for executing the operation.
This highlights the importance of execution-level controls. A control layer can reject a request before it reaches the target system. However, once the target system has accepted the request, stopping or reversing the action may necessitate a separate mechanism. A system should not report that an action has been stopped unless it has sufficient evidence to support that statement.
Tool Protocols and Guardrails Solve Different Problems
Enterprise AI systems increasingly utilize protocols and gateways to connect models with tools and business applications. These technologies can enhance integration and provide important security controls, but their roles must be correctly understood.
Model Context Protocol (MCP)
The Model Context Protocol defines a method for AI applications to connect with external tools and resources. Its authorization specification describes transport-level authorization for HTTP-based connections to protected MCP servers. The specification also notes that authorization is optional for MCP implementations, with varying guidance for HTTP and STDIO transports [3].
This is useful for controlling whether a client can access a protected server. However, transport-level authorization should not automatically be considered proof that every business action exposed by that server is properly authorized. For instance, a client may be permitted to connect to an MCP server while still being restricted from approving a payment or changing a sensitive business record. These restrictions may need to be enforced by the tool, the application, a policy service, or another control layer.
AI Safety Guardrails
AI guardrails can inspect model inputs and outputs for defined risks. Cloudflare's AI Gateway Guardrails documentation, for example, describes checks for user prompts and model responses, with configurable actions such as flagging or blocking content [4]. These controls can help mitigate certain content-related risks.
However, content inspection and business authorization are distinct tasks. A response might contain acceptable text while proposing an unauthorized business action. For example, a model might generate a clear and well-written request to change a supplier's payment details. Content moderation alone does not determine whether that change is permitted. Cloudflare also documents limitations in its guardrail implementation, including supported hazard categories and streaming behavior [5]. This serves as a reminder that security features must be assessed based on their actual scope, not just their names.
The Practical Distinction
| Control | Main question | | :------ | :------------ | | **Identity and access management** | Who or what is allowed to access a resource? | | **Protocol authorization** | Can this client access this protected service? | | **Content guardrails** | Does this input or output match defined safety rules? | | **Business authorization** | Is this specific action allowed under current policy? | | **Execution enforcement** | Can the action be blocked or limited before it takes effect? | | **Audit and evidence** | What can the organization verify about the decision and outcome? |
These controls may work in conjunction, but they should not be treated as interchangeable.
The Evidence Problem: A Log Is Not Always Proof of the Outcome
Enterprise governance demands more than merely knowing that an agent requested an action. Organizations may need to establish: - Who or what initiated the action. - Which policy was applicable. - Whether authorization was granted. - Whether human approval was required. - Which tool received the request. - Whether the target system accepted it. - Whether execution completed. - What changed as a result. - Whether a failure or cancellation occurred. - Whether the final state was verified.
Different systems may record different parts of this sequence. A model log might show what the agent proposed. An API gateway log might indicate that a request passed through. An authorization service might show that a policy decision was made. A target application might show that a record was changed. These records offer distinct types of evidence.
A record that a request was sent does not necessarily prove its success. A record that a request was accepted does not necessarily prove that the intended business outcome was achieved. The evidence must align with the claim being made.
A Useful Evidence Model
An enterprise can structure execution evidence around five questions: - **Identity:** Which agent, user, or service initiated the action? - **Authority:** Which permission or approval allowed it? - **Decision:** Which policy decision was made, and when? - **Execution:** Which system accepted and processed the request? - **Outcome:** What result can be verified?
For high-impact actions, the organization may also need to record cancellation, reversal, exception handling, or human intervention. This approach helps to distinguish what the agent said from what the enterprise system actually did. While self-reporting is useful information, it should not be the sole evidence of successful execution.
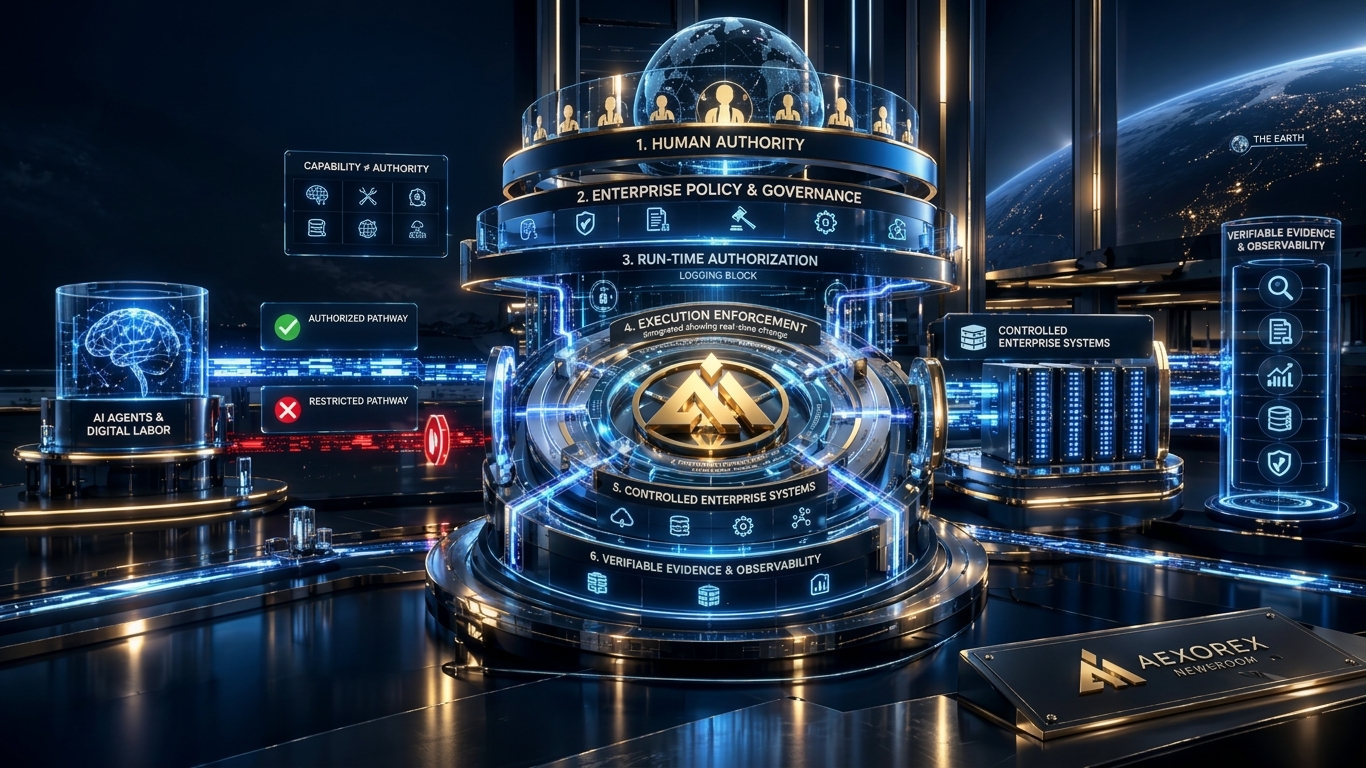
A Reference Architecture for Runtime Authority
The following architecture proposes a design model for enterprises needing to govern AI-driven actions. It does not claim that every organization requires identical components or that any single vendor provides a complete solution.
Layer 1: Human and organizational authority
This layer defines who is responsible for decisions. It includes: - Business owners. - Authorized approvers. - Risk owners. - Security teams. - Governance policies. - Escalation rules. Human authority should remain clear, even when routine tasks are automated.
Layer 2: AI agent and task planning
The AI agent interprets the request and proposes a plan. It may identify information, select available tools, and prepare actions. However, its ability to propose an action does not grant it permission to execute it.
Layer 3: Policy and authorization
This layer evaluates whether a proposed action is allowed. Depending on the organization, it may consider identity, role, resource, action type, risk, approval status, and other relevant conditions. It should return a clear decision, such as: - Allow. - Deny. - Hold. - Request approval. - Escalate.
Layer 4: Execution enforcement
This layer ensures that the authorization decision is applied to the actual request. It may reside in an API gateway, application, tool service, workflow engine, or target system. The design should avoid relying solely on the agent's promise to follow the policy.
Layer 5: Business systems and effects
This layer comprises the applications and services that perform the requested actions. Examples include accounting systems, customer databases, document platforms, and workflow tools. These systems may require their own authorization checks, particularly for high-impact operations.
Layer 6: Monitoring and evidence
This layer records and verifies what occurred. It may combine policy decisions, gateway records, workflow events, application logs, and confirmation from the target system. The goal is to support investigation, accountability, and verification of important outcomes.
How the Layers Work Together
A controlled execution process can follow this sequence: Connect → Understand the request → Check policy → Authorize → Enforce → Execute → Verify → Record evidence
The process may revert to an earlier stage if new information emerges or conditions change. Evidence should be collected throughout the process, not merely at the end. This architecture aligns with the broader security principle that access decisions must be linked to enforcement and monitoring, extending this principle to a proposed model for controlling AI-driven business actions [1].
What This Means for AEOS QUANTUM™
AEOS QUANTUM™ is being developed as an enterprise intelligence operating platform concept designed to connect, coordinate, and govern enterprise systems and digital labor. The runtime authority problem is directly relevant to this objective.
A platform engineered to coordinate AI agents should not treat an agent's technical capabilities as unlimited business authority. Instead, its architecture should differentiate between what an agent can do, what it is permitted to do, and what the organization can verify that it did.
The following principles are therefore pertinent to the planned AEOS QUANTUM™ architecture: - **Capability is not authority:** An agent may have access to a tool without being allowed to use every function offered by that tool. - **Authority must be explicit:** Permissions should be defined in terms of actions, resources, conditions, and limits, not merely broad access to an application. - **Authorization must connect to enforcement:** A policy decision has limited value if the relevant system cannot apply it to the action being requested. - **Revocation must consider execution state:** Withdrawing permission should trigger the appropriate response for new requests, queued work, running operations, and actions that have already taken effect. - **Evidence must match the claim:** A proposed action, an authorization decision, an accepted request, and a verified business result are distinct events. - **Human control must remain available:** High-impact, uncertain, or exceptional situations may require a human decision. The architecture should define when to pause, escalate, or return control to an authorized person.
These are architectural principles and design goals, not assertions that AEOS QUANTUM™ currently implements or has independently validated every control described in this article. This distinction is important: a responsible enterprise technology publication must differentiate between a proposed architecture and a deployed, tested capability.
Open Questions and Practical Challenges
Addressing runtime authority requires more than simply adding another authorization check. Several challenges persist:
12.1 Distributed systems
A single business action may involve multiple applications, services, and vendors. The organization must understand where authorization is checked and whether all relevant systems apply the required limits.
12.2 Changes during execution
Permissions may change after an action has been accepted. Systems need defined behaviors for work that is waiting, running, completed, or only partially completed.
12.3 External side effects
Some actions cannot be easily reversed. A system might be able to halt future steps but be unable to undo an external transaction that has already completed.
12.4 Evidence across vendors
Different providers may use varying event formats, retention rules, and monitoring capabilities. Organizations need a reliable method to connect these records without assuming that one log contains the entire story.
12.5 Balancing autonomy and control
If every low-risk action necessitates manual approval, automation may become inefficient. Conversely, if high-impact actions receive insufficient control, the organization may incur unnecessary risk. The appropriate balance depends on the business process, potential consequences, applicable obligations, and available safeguards.
12.6 Proving effectiveness
A design document can describe how a control should function, but it cannot, by itself, prove that the control operates effectively under real-world conditions. Testing should include scenarios involving denied actions, expired credentials, revoked permissions, unavailable policy services, interrupted workflows, and unexpected target-system responses. The organization should also verify that its evidence records support the conclusions drawn from them.
Conclusion: Authority Must Survive Contact with Execution
Enterprise AI governance cannot end with defining what an agent should be allowed to do. It must also establish how that permission is checked, where it is enforced, what occurs when permission changes, and how the resulting actions are verified.
The key distinction is simple: - An agent may be capable of performing an action without being authorized to perform it. - An authorization decision may be valid without proving that the action succeeded. - A revocation request may be accepted without proving that every operation already in progress has stopped. - A log may record an event without proving the complete business outcome.
These are distinct problems requiring interconnected controls. The runtime authority problem thus calls for an architecture where policy, execution, containment, and evidence are intrinsically linked. For enterprise AI, the goal should not be autonomy without limits. It should be autonomy that operates within defined authority, remains subject to enforcement, and produces evidence that supports accountability.
The central principle is this: AI agents may act autonomously only within authority that the enterprise has defined, enforced, and can verify. For AEOS QUANTUM™, this principle underpins a broader architectural direction: connecting enterprise systems, coordinating digital labor, enforcing defined authority, and preserving human control where required. The challenge is not merely to enhance AI agents' capabilities but to ensure their actions are governable.
Sources and attribution
- AexoreX Systems — Original Editorial Research · statement link
About the author
Research desk of AexoreX Newsroom.
More from AexoreX Research Desk →Related stories
- The Non-Human Authorization Crisis: Re-Architecting Identity, Governance, and Execution for Autonomous Enterprise Systems
- The Runtime Authority Control Plane: Why Enterprise AI Needs More Than Identity and Permissions
- From Autonomous Execution to Enterprise Evidence
- EXECUTION-TIME AUTHORITY ATTENUATION
- Beyond AI: Building the Enterprise Operating Model for Intelligence, Digital Labor, Governance, and Execution.
- From Agent Interoperability to Governed Execution: Why Enterprise AI Needs an Authority Layer
- The Evidence Sufficiency Problem: From Trustworthy Records to Verifiable Enterprise Outcomes
- The Runtime Enforcement Gap: From Authorized Intent to Verifiable Execution
- THE EXECUTION CONTINUITY PROBLEM
- The Reconciliation Authority Problem